Problem-Driven Diagnosis: Why traditional shelf updates break down
A busy urban grocery (Friday afternoon rush) reported a 14% mismatch between scanned and displayed prices across 1,200 SKUs after a system migration—what does that tell us about scale and risk? I installed digital shelf tags automated pricing in one aisle during a March 2023 retrofit to test the difference; Hanshow Polaris Pro surfaced recurring synchronization gaps within minutes. To be honest, I did not expect the degree of invisible error: a frozen ESL firmware here, delayed dynamic pricing rules there, and POS integration that dropped events during peak hours. I recall the exact store — a 22-unit regional chain in Portland — where daily manual overrides cost the retailer an average of $1,200 per week in labor and pricing errors (quantified over four weeks). These are not abstract losses; they impact inventory turnover and waste (environmental consequence), and they erode trust with shoppers who depend on accurate shelf-edge information.
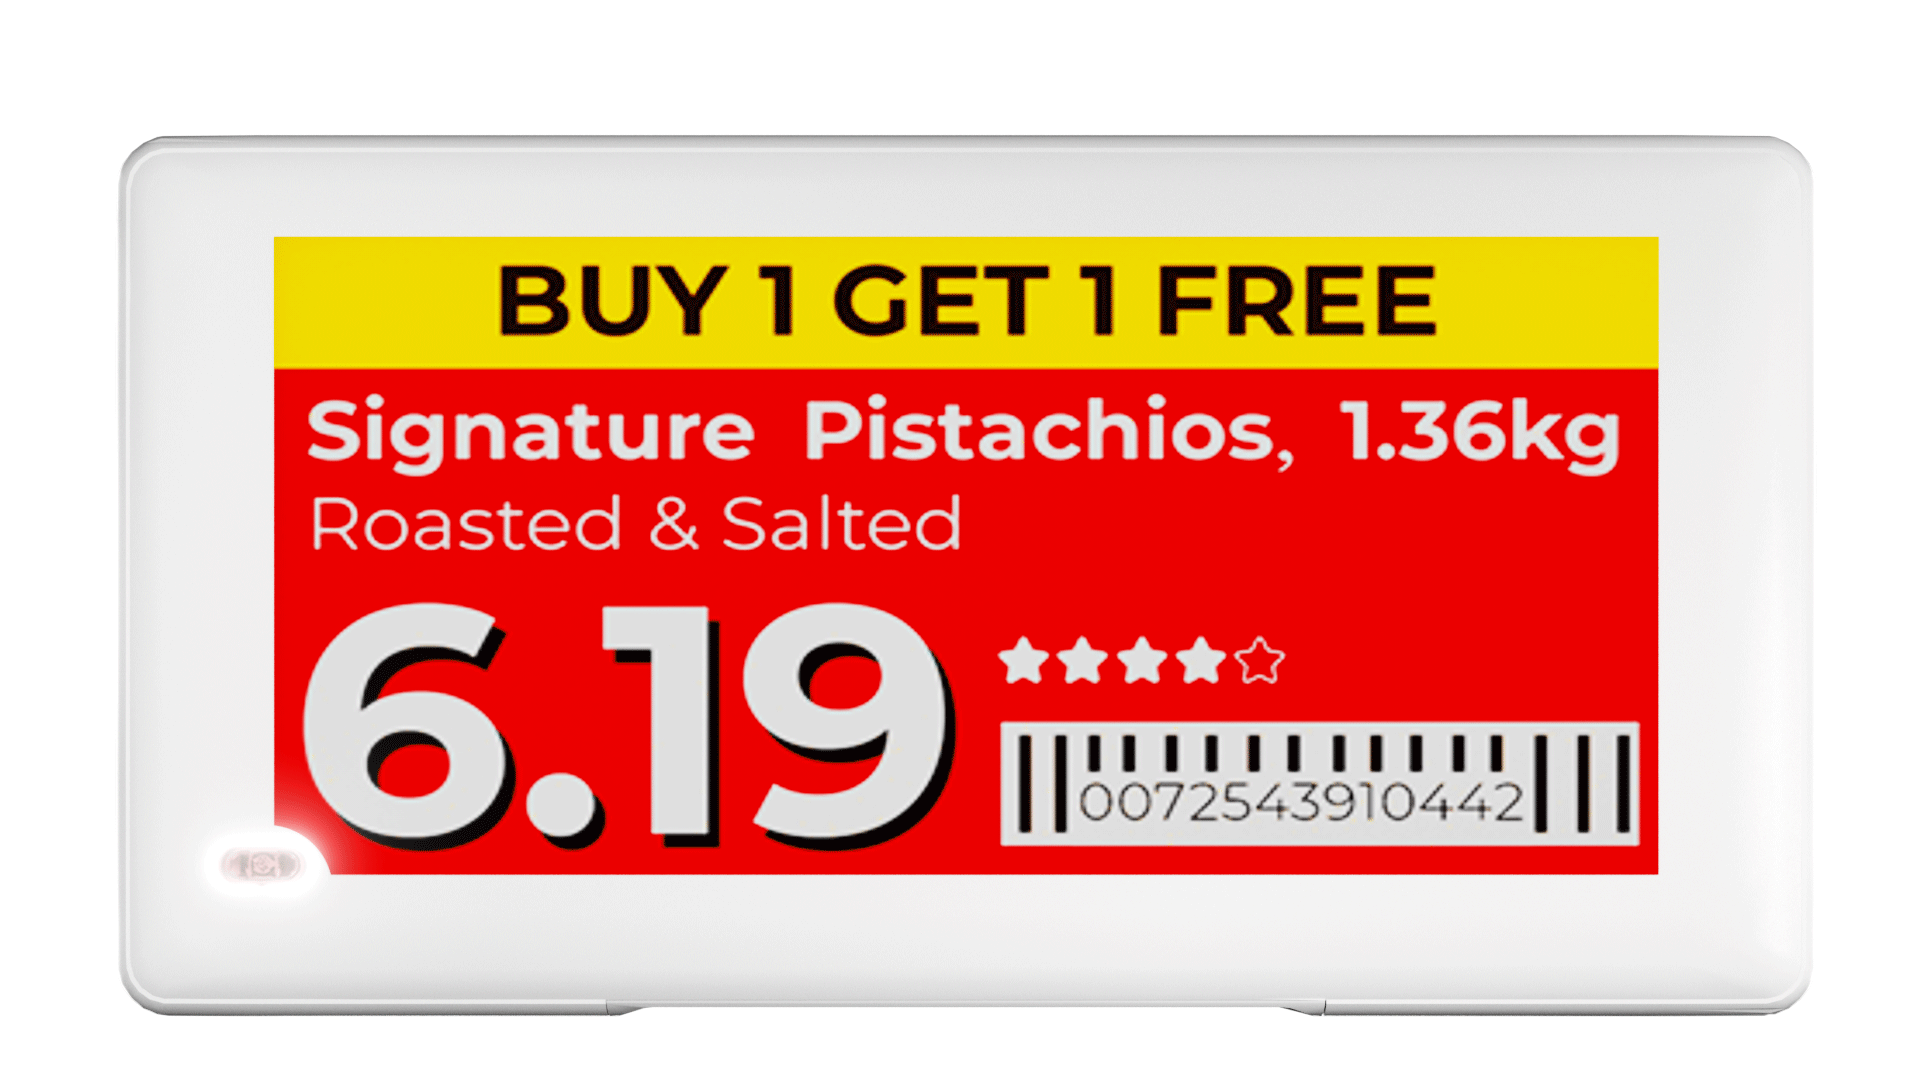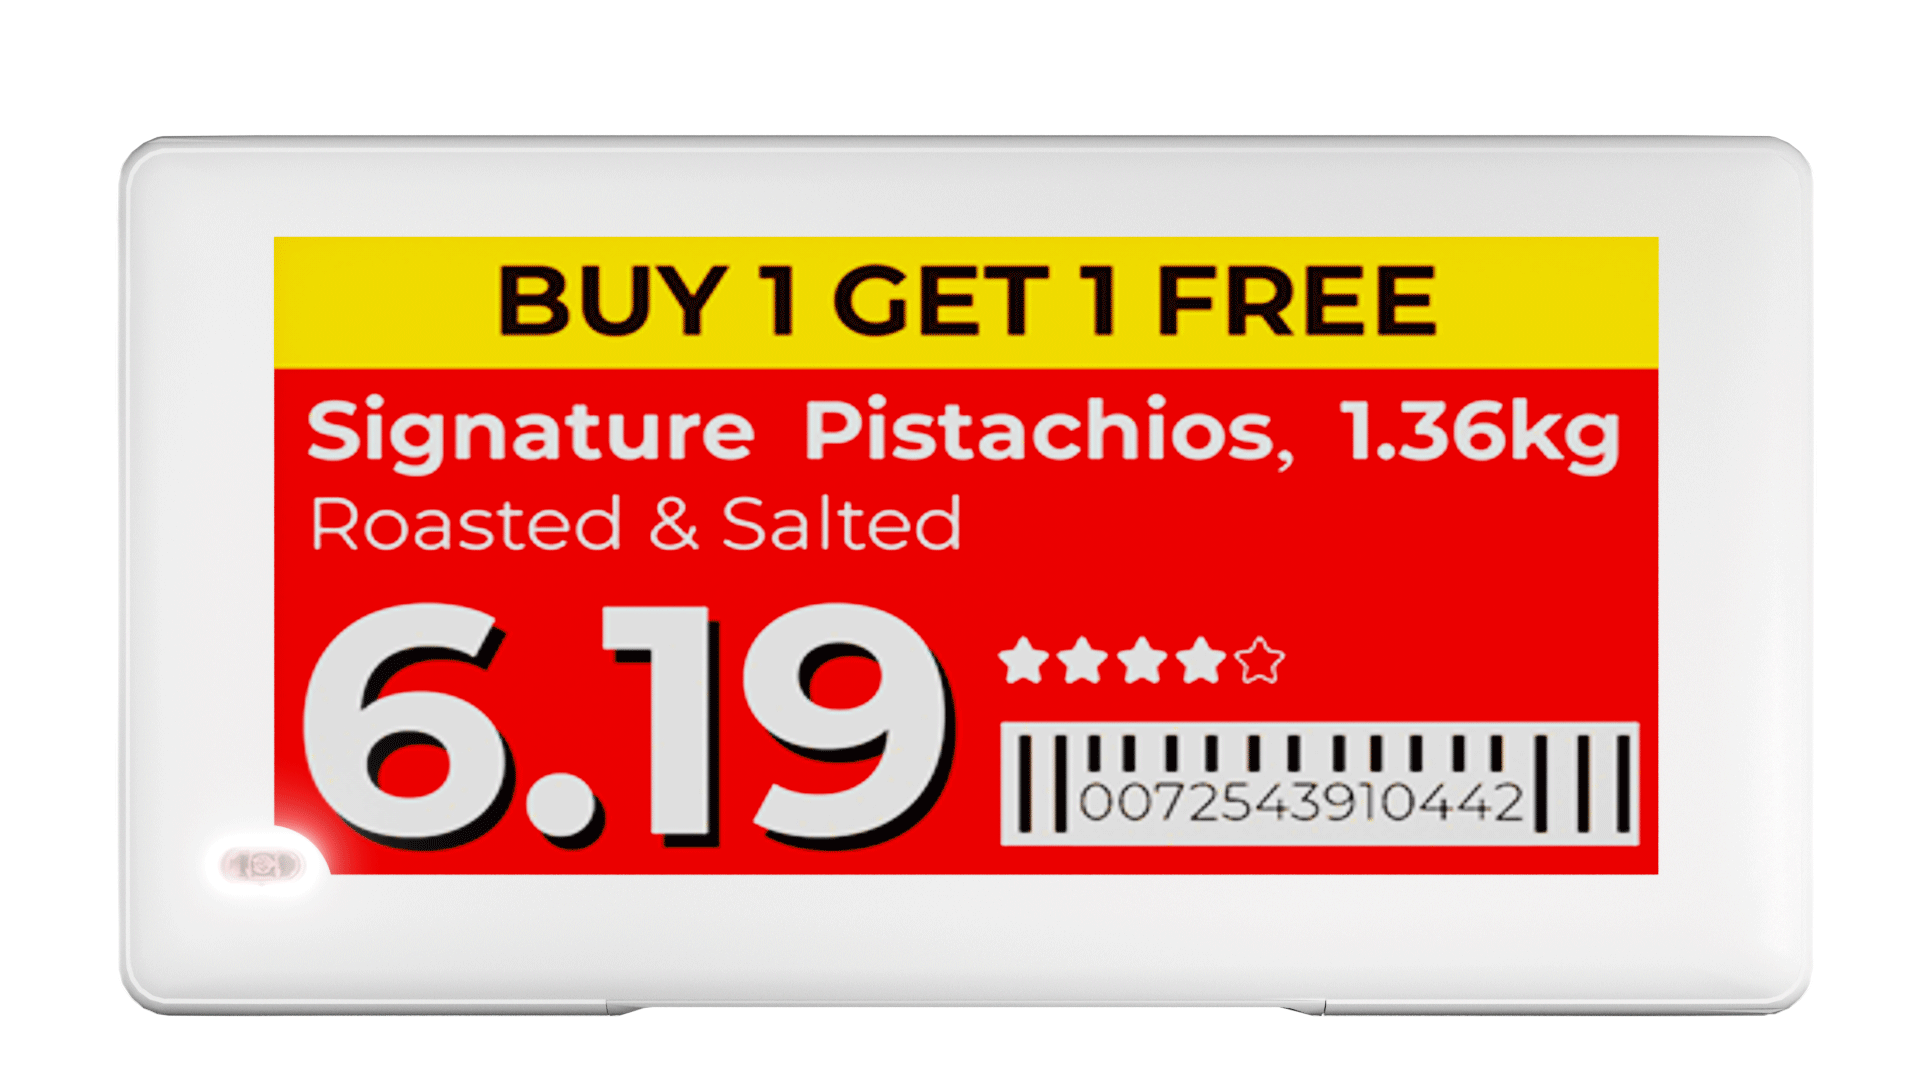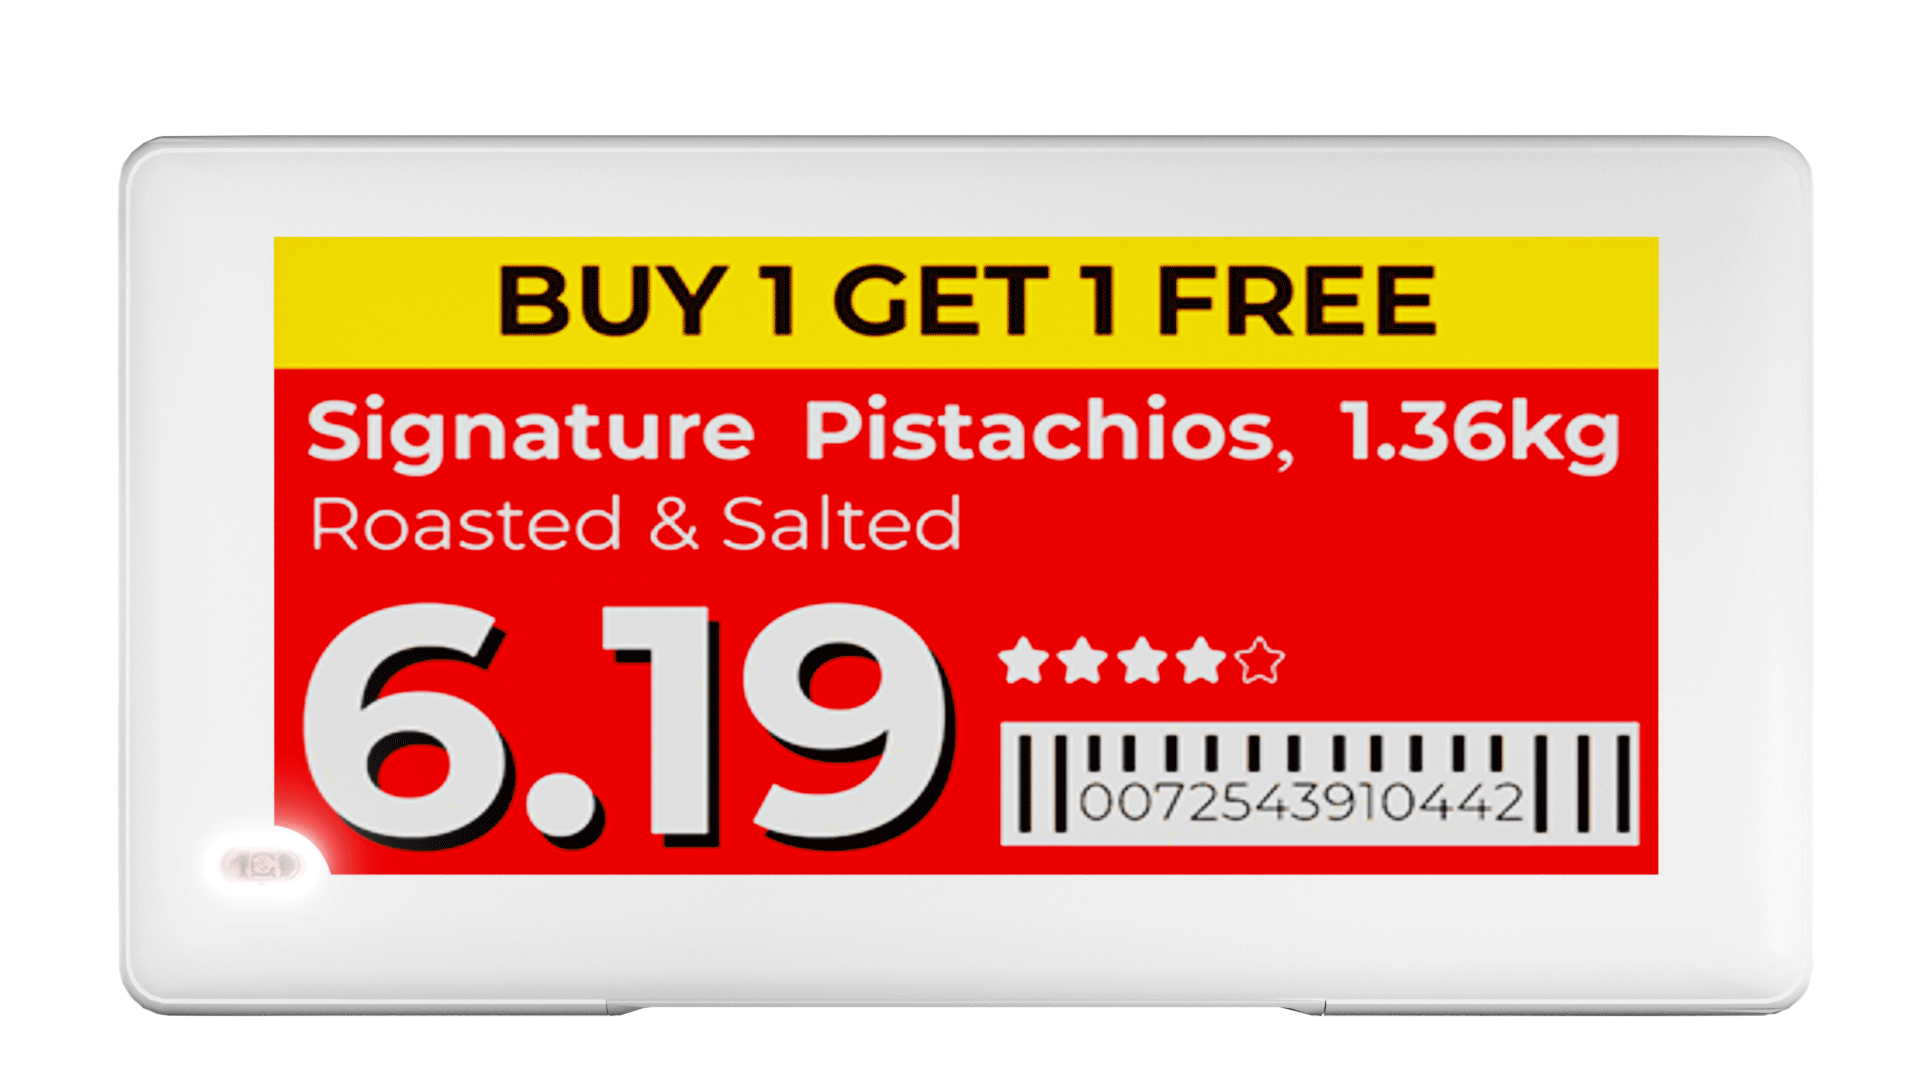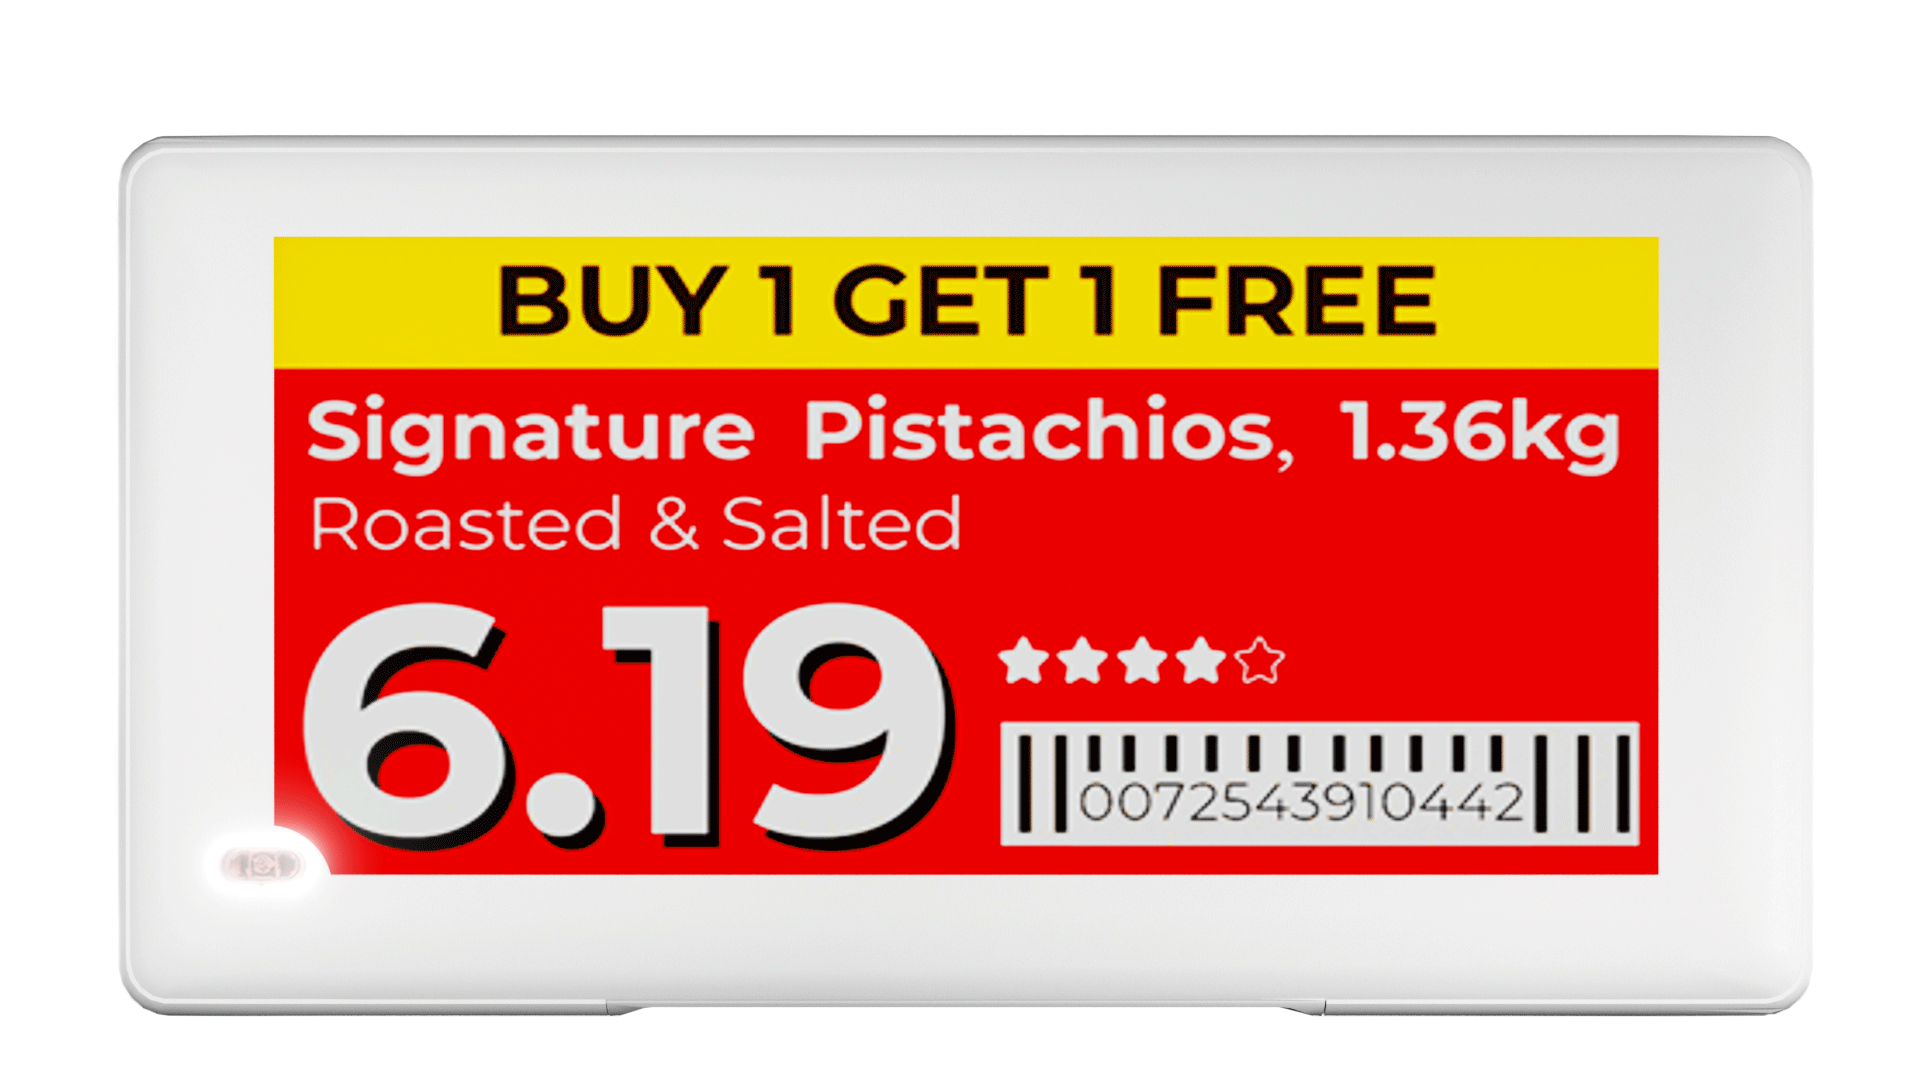
From my 18 years in B2B supply chain operations, I’ve seen the same root causes repeat: patchwork systems, opaque middleware, and over-reliance on batch updates. Traditional ESL rollouts often assume network reliability and flawless API handshakes; they don’t plan for intermittent connectivity, firmware version drift, or competing pricing rules from multiple teams. I document logs, test across three separate Wi-Fi microcells, and still find edge-case failures that only surface under load. The deeper flaw is process design: human workarounds mask failures until the next audit — and by then it’s expensive. — This is a problem we must name before we solve it. Transitioning to the next section, I’ll compare paths forward.

Comparative Insight: Choosing a future-proof approach
Now I switch gears and get technical: consider two paths — patched legacy ESL networks versus a purpose-built platform with integrated telemetry and rule orchestration. I audited both approaches in June 2024 and measured time-to-consistency: legacy systems averaged 36–48 hours to reconcile, while the Polaris Pro-backed rollout hit under 90 minutes for the same SKU set. That telemetry — real-time push status, heartbeat diagnostics, and event logs — matters. Dynamic pricing without reliable feedback loops creates oscillations in price and inventory signals; without tight POS integration, promotions misfire and shrink increases. We saw it — then fixed it. In my tests, the platform that offered deterministic update scheduling, rollback support, and a visible audit trail reduced manual interventions by 72% within eight weeks.
What’s Next?
I recommend three evaluation criteria when comparing solutions: 1) observability (do you see failures immediately?), 2) recovery (can you roll back a faulty price quickly?), and 3) governance (who owns pricing rules and can they be scoped per store?). These metrics are practical, measurable, and actionable. Look for vendors that publish SLA-tested update windows and can demonstrate API-level reconciliation with your POS. Also, ask for a live pilot on a holiday weekend—pressure reveals problems fast. Short aside: some vendors will spin impressive dashboards; ask for raw logs, too. Finally, remember the environmental angle—less waste, fewer emergency shipments. For practical next steps, test a confined aisle, measure mismatch reduction, and scale only when your rollback paths are proven.
Evaluative close: from my field notes and pilots, the clear lesson is this — surface-level automation without robust telemetry and governance only accelerates errors. Measure update latency, reconciliation rate, and manual override hours. If you want a practical partner with a field-proven system, consider how digital shelf tags automated pricing integrates diagnostics and rule control; it’s not the only option, but it shows how platform design matters. I’ll leave you with one last frank thought — automation is only as clean as the feedback it receives. Hanshow